For the complete documentation index, see llms.txt. Markdown versions of all docs pages are available by appending .md to any docs URL.
vLLM Semantic Router
Route LLM requests by prompt semantics with vLLM Semantic Router and agentgateway.
vLLM Semantic Router (vSR) classifies LLM requests and selects a model based on prompt content. With agentgateway, you can make this semantic decision before routing while continuing to apply gateway policies and record model, token, latency, and cost telemetry. See the vSR Router API reference for supported frontend and backend API types.
This integration is distinct from using vLLM as an inference provider. vSR provides the model-selection policy while your configured backend serves the selected model.
For inference with vLLM, see vLLM as an inference provider.
How the integration works
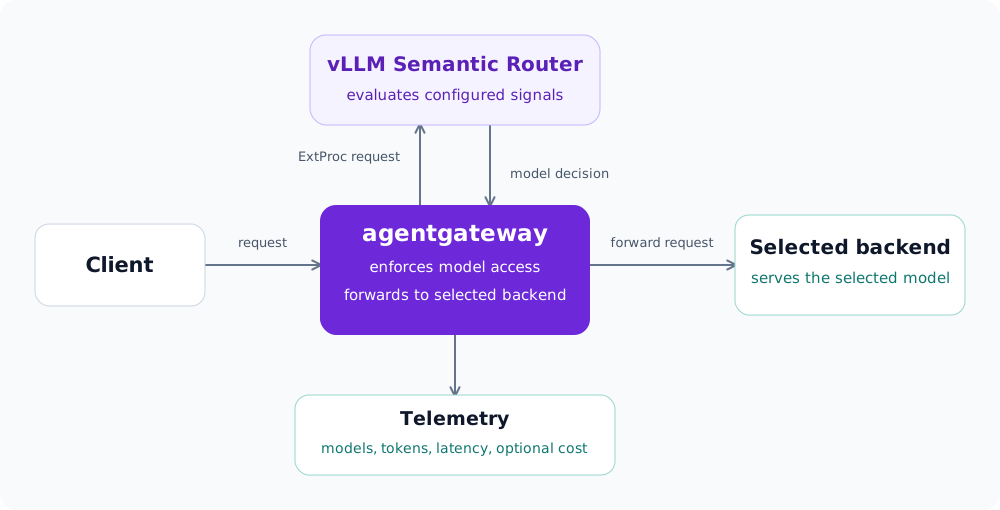
- Process the request: A client sends an LLM request to agentgateway, which calls vSR as an external processor (ExtProc) during
PreRouting, before model selection. - Select a model: vSR evaluates its configured signals, such as prompt content or caller tier, and returns a processing response that updates the request’s
modelfield. - Forward the request: Agentgateway uses the selected model to choose a configured backend, applies gateway policies such as model authorization, and forwards the request for inference. Agentgateway records usage and latency for observability.
When response caching is enabled, vSR can return a cached completion through ExtProc, allowing agentgateway to respond without calling the backend.
Choose an integration path
Use the following guides and examples to configure the integration.
The single-runtime example uses AgentgatewayModel resources and requires agentgateway v1.5.0 or later, matching CRDs, and the experimental model API setting documented in its README.
To request an additional integration example, create an issue in the agentgateway repository and describe your use case.
Integration considerations
Client model selection: The examples use
model: "auto"to opt in to semantic selection. This value is an example policy convention, not a reserved agentgateway model. If clients can request models explicitly, enforce model entitlements in agentgateway as well as in vSR decisions. You can validate the request body to require the automatic path.Backend choice: vSR can select models served by hosted providers or self-hosted inference workloads. Configure the corresponding LLM provider or routing backend in agentgateway.
Model names: Keep the names returned by vSR aligned with the models in your agentgateway routes, provider configuration, and cost catalog. You can expose stable client-facing names with model aliases.
Trusted tier context: The single-runtime examples use caller-supplied user ID and tier headers to demonstrate routing, not authentication. Before exposing them to users, validate identity and bind those headers to trusted entitlements before ExtProc runs. API key authentication alone does not verify a caller-supplied tier.
Cost and observability: vSR makes the semantic decision. Agentgateway remains the source for completed-request telemetry and can calculate realized cost when you configure a model cost catalog. Use LLM metrics and logs or the OpenTelemetry stack to evaluate the result.
Before a broad rollout, compare routed traffic with a fixed higher-capability-model baseline. Confirm that the policy uses the intended model tiers, then evaluate task completion, user feedback, retries, and escalation rates alongside cost and latency.